


This browser is too old to run Achievable.

Update it, or open this page in a current version of Chrome, Safari, Firefox or Edge. On an iPhone or iPad, update iOS: every browser there runs on the version of Safari that comes with it.

Achievable logoAchievable logo
CMA Part 1
Sign in
Sign up
Purchase
Textbook
Practice exams
Support
How it works
Resources
Exam catalog
Mountain with a flag at the peak
Textbook
Introduction
1. External financial reporting decisions
2. Planning, budgeting, and forecasting
3. Performance management
4. Cost management
5. Internal control
6. Technology and analytics
Wrapping up
Achievable logoAchievable logo
6.3.4.1 Introduction to types of data analytics
Achievable CMA Part 1
6. Technology and analytics
6.3. Data analytics
6.3.4. Types of data analytics
Our CMA Part 1 course is currently in development and is a work-in-progress.

Introduction to types of data analytics

4 min read
Font
Discuss
Share
Feedback

Learning outcome statements

The learning outcome statements relevant for this section are:

  1. explain the challenge of fitting an analytics model to the data
  2. define the different types of data analytics, including descriptive, diagnostic, predictive, and prescriptive
  3. define clustering and classification, and determine when each of these analytic techniques would be the appropriate tool to use

Types of data analytics

One of the fundamental challenges in data analytics is ensuring that the chosen analytical model fits the available data appropriately. If a model is too simple, it may fail to capture important relationships (underfitting), leading to inaccurate predictions. Conversely, if a model is too complex, it may fit the training data perfectly but fail to generalize to new data (overfitting). Analysts must balance complexity and interpretability, selecting models that provide meaningful insights without unnecessary complexity.

Analysts test for fit by checking the model against data it was not built from (a holdout or validation set): an overfit model scores well on training data but poorly on new data, while an underfit model scores poorly on both. For example, a model that predicts its own training data with near-perfect accuracy but performs poorly on new, unseen data is a classic case of overfitting.

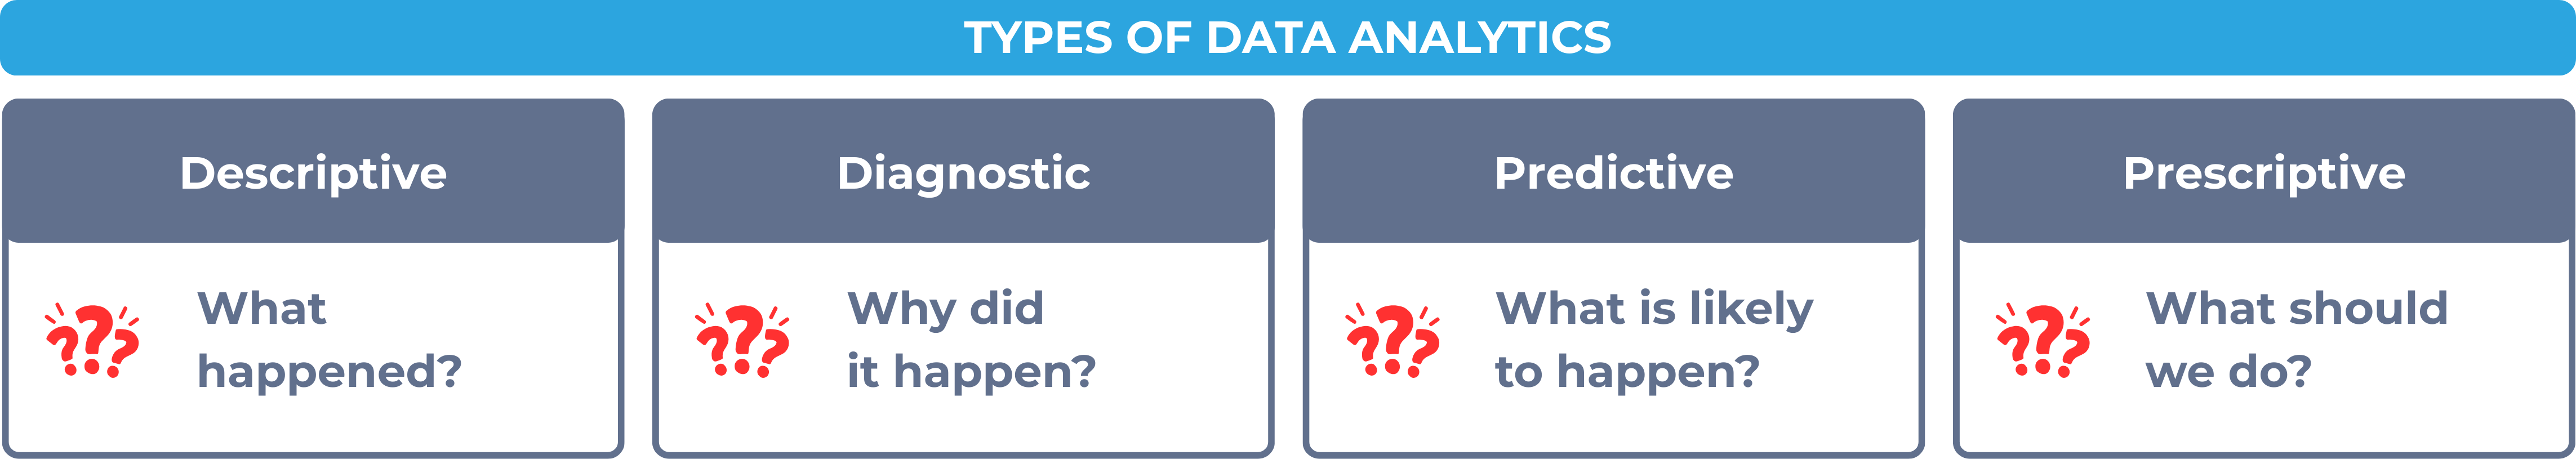
Data analytics can be categorized into four primary types, each serving a distinct purpose:

The four types build on one another: descriptive and diagnostic analytics look backward (hindsight), while predictive and prescriptive analytics look forward (foresight). Complexity and potential value rise from descriptive to prescriptive; predictive analytics forecasts what’s likely to happen, and prescriptive analytics goes one step further to recommend what to do about it.

Types of data analytics

Descriptive analytics

This type focuses on summarizing historical data to understand past trends and performance. This type of analytics helps answer questions such as, “What happened?”

For example, a company may analyze sales data to determine which products performed best in a given quarter. Descriptive analytics is typically done with spreadsheets, SQL, and BI dashboards.

Diagnostic analytics

This type examines data to determine why a particular event occurred. It answers the question, “Why did it happen?”

For instance, a manufacturing company may investigate production delays by analyzing equipment downtime, raw material shortages, and labor efficiency.

Predictive analytics

This type uses statistical models and machine learning techniques to forecast future trends based on historical data. It helps answer, “What is likely to happen?”

An example is a financial institution using predictive analytics to assess credit risk by analyzing customer credit histories, spending behaviors, and economic indicators.

Prescriptive analytics

This type provides actionable recommendations based on data insights, often using optimization algorithms and simulations. It answers the question, “What should we do?”

For example, an airline may use prescriptive analytics to determine optimal pricing strategies based on demand forecasts and competitor pricing.

Clustering vs. classification

Two widely used techniques in data analytics are clustering and classification:

  • Clustering is an unsupervised learning technique that groups data points based on similarity without predefined categories. It is useful for market segmentation, customer profiling, and anomaly detection. For example, a retailer may use clustering to identify customer segments based on purchasing behavior.
  • Classification is a supervised learning technique that assigns data points to predefined categories based on labeled training data. It is commonly used for fraud detection, sentiment analysis, and medical diagnoses. For instance, banks use classification models to distinguish between fraudulent and legitimate transactions.

Choosing between clustering and classification depends on whether predefined labels exist in the dataset. If the goal is to discover hidden patterns without prior labels, clustering is appropriate. If the objective is to categorize data into known classes, classification is the better choice.

Model fit challenges

  • Underfitting: model too simple, misses relationships, inaccurate predictions
  • Overfitting: model too complex, fits training data perfectly but fails to generalize
  • Test fit using holdout/validation set (data not used in training)
  • Goal: balance complexity and interpretability

Four types of data analytics

  • Progress from hindsight to foresight, increasing complexity/value: descriptive → diagnostic → predictive → prescriptive
  • Descriptive (“What happened?”): summarizes historical data/trends; tools include spreadsheets, SQL, BI dashboards
  • Diagnostic (“Why did it happen?”): investigates causes behind events (e.g., production delays)
  • Predictive (“What is likely to happen?”): uses statistics/ML to forecast future trends (e.g., credit risk assessment)
  • Prescriptive (“What should we do?”): recommends actions via optimization/simulation (e.g., pricing strategy)

Clustering vs. classification

  • Clustering: unsupervised, groups similar data without predefined categories; used for market segmentation, anomaly detection
  • Classification: supervised, assigns data to predefined labeled categories; used for fraud detection, medical diagnosis
  • Choice depends on whether predefined labels exist: no labels → clustering; known categories → classification

Sign up for free to take 9 quiz questions on this topic

Previous
Next  | 6.3.4.2 Regression and statistical methods
All rights reserved ©2016 - 2026 Achievable, Inc.

Introduction to types of data analytics

Learning outcome statements

The learning outcome statements relevant for this section are:

  1. explain the challenge of fitting an analytics model to the data
  2. define the different types of data analytics, including descriptive, diagnostic, predictive, and prescriptive
  3. define clustering and classification, and determine when each of these analytic techniques would be the appropriate tool to use

Types of data analytics

One of the fundamental challenges in data analytics is ensuring that the chosen analytical model fits the available data appropriately. If a model is too simple, it may fail to capture important relationships (underfitting), leading to inaccurate predictions. Conversely, if a model is too complex, it may fit the training data perfectly but fail to generalize to new data (overfitting). Analysts must balance complexity and interpretability, selecting models that provide meaningful insights without unnecessary complexity.

Analysts test for fit by checking the model against data it was not built from (a holdout or validation set): an overfit model scores well on training data but poorly on new data, while an underfit model scores poorly on both. For example, a model that predicts its own training data with near-perfect accuracy but performs poorly on new, unseen data is a classic case of overfitting.

Data analytics can be categorized into four primary types, each serving a distinct purpose:

The four types build on one another: descriptive and diagnostic analytics look backward (hindsight), while predictive and prescriptive analytics look forward (foresight). Complexity and potential value rise from descriptive to prescriptive; predictive analytics forecasts what’s likely to happen, and prescriptive analytics goes one step further to recommend what to do about it.

Descriptive analytics

This type focuses on summarizing historical data to understand past trends and performance. This type of analytics helps answer questions such as, “What happened?”

For example, a company may analyze sales data to determine which products performed best in a given quarter. Descriptive analytics is typically done with spreadsheets, SQL, and BI dashboards.

Diagnostic analytics

This type examines data to determine why a particular event occurred. It answers the question, “Why did it happen?”

For instance, a manufacturing company may investigate production delays by analyzing equipment downtime, raw material shortages, and labor efficiency.

Predictive analytics

This type uses statistical models and machine learning techniques to forecast future trends based on historical data. It helps answer, “What is likely to happen?”

An example is a financial institution using predictive analytics to assess credit risk by analyzing customer credit histories, spending behaviors, and economic indicators.

Prescriptive analytics

This type provides actionable recommendations based on data insights, often using optimization algorithms and simulations. It answers the question, “What should we do?”

For example, an airline may use prescriptive analytics to determine optimal pricing strategies based on demand forecasts and competitor pricing.

Clustering vs. classification

Two widely used techniques in data analytics are clustering and classification:

  • Clustering is an unsupervised learning technique that groups data points based on similarity without predefined categories. It is useful for market segmentation, customer profiling, and anomaly detection. For example, a retailer may use clustering to identify customer segments based on purchasing behavior.
  • Classification is a supervised learning technique that assigns data points to predefined categories based on labeled training data. It is commonly used for fraud detection, sentiment analysis, and medical diagnoses. For instance, banks use classification models to distinguish between fraudulent and legitimate transactions.

Choosing between clustering and classification depends on whether predefined labels exist in the dataset. If the goal is to discover hidden patterns without prior labels, clustering is appropriate. If the objective is to categorize data into known classes, classification is the better choice.

Key points

Model fit challenges

  • Underfitting: model too simple, misses relationships, inaccurate predictions
  • Overfitting: model too complex, fits training data perfectly but fails to generalize
  • Test fit using holdout/validation set (data not used in training)
  • Goal: balance complexity and interpretability

Four types of data analytics

  • Progress from hindsight to foresight, increasing complexity/value: descriptive → diagnostic → predictive → prescriptive
  • Descriptive (“What happened?”): summarizes historical data/trends; tools include spreadsheets, SQL, BI dashboards
  • Diagnostic (“Why did it happen?”): investigates causes behind events (e.g., production delays)
  • Predictive (“What is likely to happen?”): uses statistics/ML to forecast future trends (e.g., credit risk assessment)
  • Prescriptive (“What should we do?”): recommends actions via optimization/simulation (e.g., pricing strategy)

Clustering vs. classification

  • Clustering: unsupervised, groups similar data without predefined categories; used for market segmentation, anomaly detection
  • Classification: supervised, assigns data to predefined labeled categories; used for fraud detection, medical diagnosis
  • Choice depends on whether predefined labels exist: no labels → clustering; known categories → classification

More from Types of data analytics

  • Regression and statistical methods
  • Time series analysis
  • Exploratory data analysis
  • Sensitivity analysis
  • Simulation models